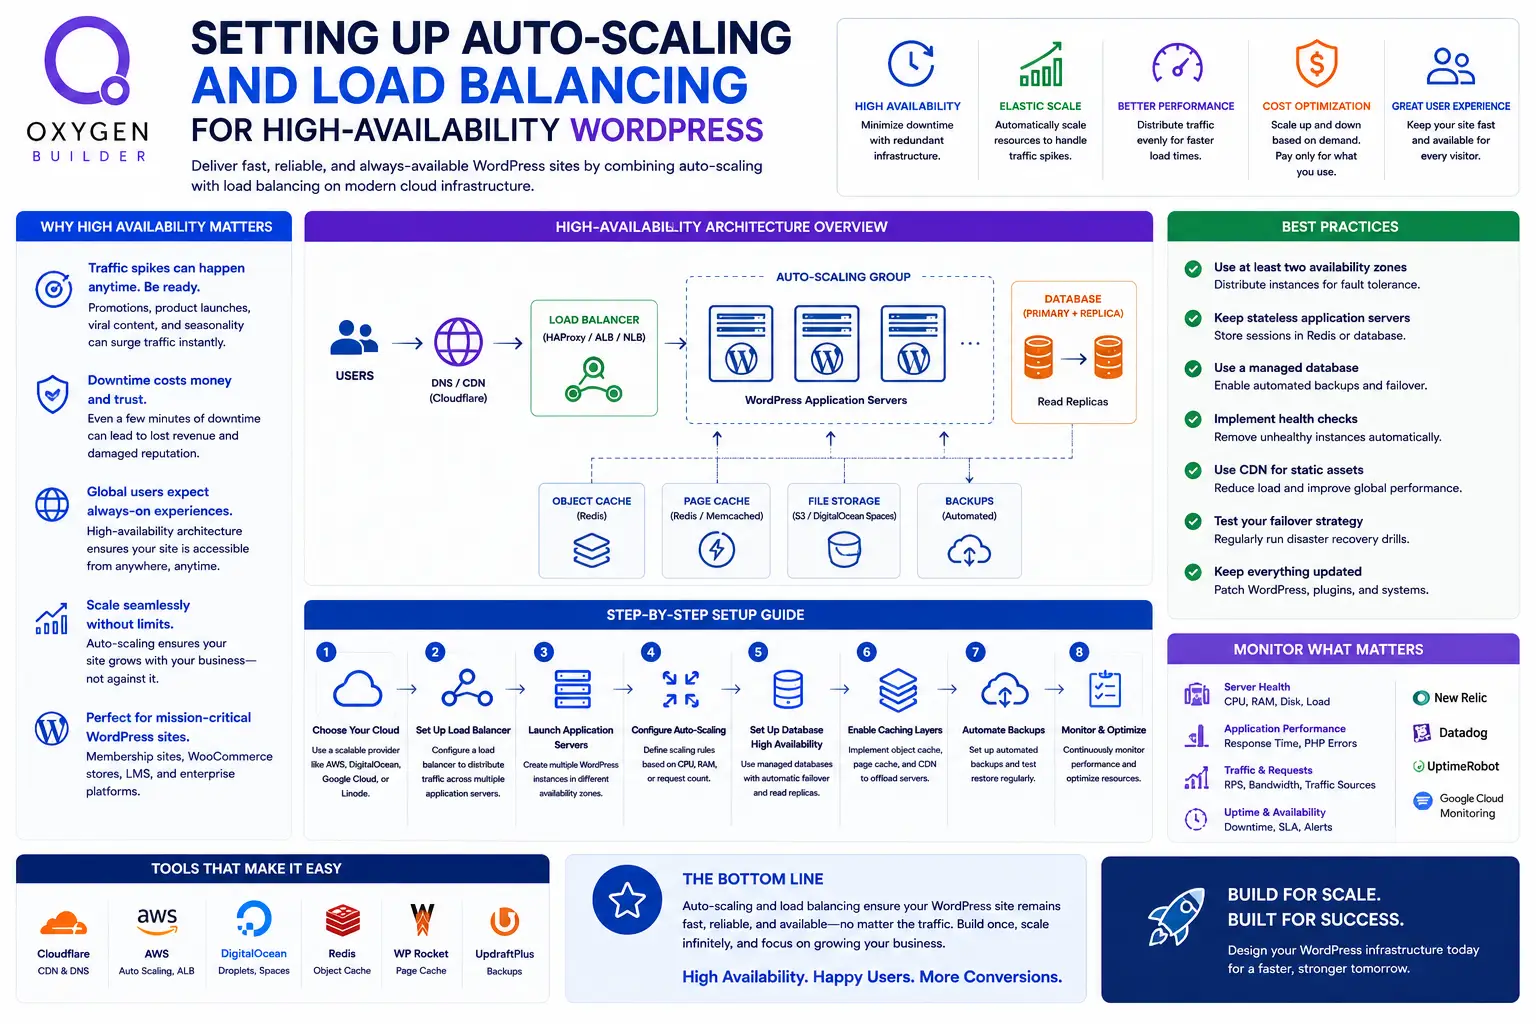
A traffic spike rarely takes WordPress down by exhausting CPU. It takes it down because PHP-FPM runs out of workers, requests queue, the queue times out at the proxy, and every visitor gets a 502 while the CPU graph sits at 40 percent looking healthy. A second server fixes that, and a second server is where WordPress stops cooperating.
This is the build rather than the concept: what you configure, in what order, the WordPress changes that must come first, the thresholds that make scaling policies behave, and the five things that break in production.
Disclosure: some links in this article are affiliate links. If you buy through them we may earn a commission at no extra cost to you. It does not change what we recommend.
What you are actually building
- An application load balancer with a target group, terminating TLS and distributing requests.
- An auto scaling group of identical instances built from a launch template.
- External state: database, uploads and object cache all moved off the instances.
- One scheduler, because cron on a pool runs once per server unless you stop it.
Skip the third and you get a site that half works: a visitor uploads an image, it lands on instance 2, and every later request routed to instance 1 shows a broken image. That is the failure people find in week two, in production.
Make WordPress stateless first
Do this before creating a load balancer. An instance must be disposable: terminate it at any moment and lose nothing.
The database moves to a managed instance such as RDS or Cloud SQL on a private subnet. Point wp-config.php at it through environment variables so one machine image serves staging and production.
/** Database lives off the instance. Values injected by the launch template. */
define( 'DB_NAME',     getenv( 'WP_DB_NAME' ) );
define( 'DB_USER',     getenv( 'WP_DB_USER' ) );
define( 'DB_PASSWORD', getenv( 'WP_DB_PASSWORD' ) );
define( 'DB_HOST',     getenv( 'WP_DB_HOST' ) ); // RDS writer endpoint

/** The balancer terminates TLS, so WordPress must be told the request was HTTPS. */
if ( isset( $_SERVER['HTTP_X_FORWARDED_PROTO'] ) && 'https' === $_SERVER['HTTP_X_FORWARDED_PROTO'] ) {
    $_SERVER['HTTPS'] = 'on';
}

/** Shared object cache: every node talks to the same Redis endpoint. */
define( 'WP_REDIS_HOST',   getenv( 'WP_REDIS_HOST' ) );
define( 'WP_REDIS_PREFIX', 'prod:' );
define( 'WP_CACHE',        true );

/** Nothing writes to the instance filesystem. */
define( 'DISALLOW_FILE_MODS', true );
define( 'DISALLOW_FILE_EDIT', true );

/** Cron runs from one place, not from every node. */
define( 'DISABLE_WP_CRON', true );
The X-Forwarded-Proto block is the one people omit. Without it WordPress sees plain HTTP behind the balancer, emits HTTP URLs on an HTTPS page, and you get a redirect loop that looks like a certificate fault.
Uploads go to S3 or Google Cloud Storage with a CDN in front, so media never touches instance disk. Rewrite media URLs to the CDN origin rather than the bucket, so the bucket can move later without a database find and replace. Test image processing too: some optimisation plugins read a file back off local disk straight after writing it, and offloading breaks that silently.
Redis on a managed endpoint, shared by every node, removes the repeated database queries that actually saturate a WordPress instance and gives you somewhere consistent for anything session-shaped. Set a key prefix per environment: a staging node pointed at production Redis corrupts live cache.
Build the load balancer and target group
- Create an application load balancer across at least two availability zones, with the certificate on an HTTPS listener.
- Redirect port 80 to 443 at the balancer, not in PHP. A redirect handled in WordPress costs a full request through the stack.
- Create a target group of type instance, HTTP on port 80, using the health check below.
- Point DNS at the balancer and retire any record still resolving to an instance.
A health check that proves WordPress is serving
The default check requests / and accepts a 200. On a node running full page caching that is useless: nginx serves a cached homepage with a 200 while PHP is dead and the database is unreachable, so the balancer keeps feeding a broken instance because the front page still renders.
Add an endpoint that touches what matters, as a must-use plugin so it cannot be deactivated:
<?php
/**
 * wp-content/mu-plugins/healthz.php
 * Returns 200 only if the database and object cache are both answering.
 */
add_action( 'parse_request', function () {

    if ( '/healthz' !== strtok( $_SERVER['REQUEST_URI'], '?' ) ) {
        return;
    }

    nocache_headers();
    header( 'Content-Type: text/plain' );

    global $wpdb;
    $db_ok = ( '1' === $wpdb->get_var( 'SELECT 1' ) );

    $cache_ok = true;
    if ( wp_using_ext_object_cache() ) {
        wp_cache_set( 'probe', 'ok', 'healthz', 30 );
        $cache_ok = ( 'ok' === wp_cache_get( 'probe', 'healthz' ) );
    }

    status_header( $db_ok && $cache_ok ? 200 : 503 );
    echo 'db=' . ( $db_ok ? 'ok' : 'fail' ) . ' cache=' . ( $cache_ok ? 'ok' : 'fail' );
    exit;
} );
Exclude /healthz from page caching, or you cache a 200 and defeat the point. Then check it every 15 seconds with a 5 second timeout, 2 successes to mark healthy and 3 failures to mark unhealthy. Three failures removes a broken node in about 45 seconds while surviving one slow response. One failure is too twitchy and pulls healthy instances out during a burst.
The auto scaling group and its policies
The launch template defines the image, instance type, security group, IAM role, subnets across two zones and a user data script that injects the environment variables above.
Set the group minimum to 2, not 1. A minimum of one defeats the exercise: that instance failing its health check leaves nothing serving while a replacement boots. Two instances in two zones is the smallest genuinely available configuration.
Scale on requests per target, not CPU. WordPress hits worker exhaustion long before high CPU, so a CPU policy scales out after the site has started erroring. Load test one instance to find where response time climbs and take about 70 percent of it: if a node holds 90 requests per second before the 95th percentile degrades, target 60.
Keep CPU as a secondary net at 60 percent, not 80. The gap to 100 is the runway while a new instance boots and passes two health checks, realistically three to five minutes. Trigger at 80 and the pool saturates before help arrives.
- Instance warm-up 300 seconds. Ignore a new node’s metrics until its opcode cache is warm, or the group reads it as idle and scales straight back in.
- Scale out fast, scale in slowly. Capacity is cheap and reversible; removing it during the gap between two waves is not.
- Connection draining 60 to 120 seconds, so a terminating node finishes in-flight requests rather than cutting off a checkout.
- Set a maximum. It is the only thing between a runaway crawl and a five figure invoice.
The five things that break in production
1. WP-Cron fires on every instance
WordPress triggers cron on page load, so six instances can fire the same event at once. On WooCommerce that can mean six attempts at one subscription renewal. Disable it as above and run the queue from one place: a small utility host outside the scaling group.
# On a single utility host, never on an instance inside the scaling group.
*/5 * * * * /usr/local/bin/wp cron event run --due-now --path=/var/www/html --quiet
An external scheduler calling wp-cron.php through the balancer also works, accepting that the request lands on whichever node the balancer picks. Fine for cache warming, unacceptable for anything that must run exactly once.
2. Plugins that write to local disk
Anything writing outside the uploads offload is writing to a machine that will be terminated: logs, generated CSS, cached sitemaps, backup archives, imports. The symptom is a feature that works, then does not, depending on which node answered. Audit for it: run the site a day, diff one instance against the base image, and move or remove whatever appeared.
3. Sticky sessions for carts and logins
If cart and session state lives in the database or shared Redis, any node serves any request and you need no stickiness at all. That is the target. Where a plugin insists on PHP native sessions, enable stickiness with a short duration and treat it as an accommodation, not the architecture: it undermines even distribution, and removing an instance drops the sessions pinned to it.
4. Deploying to a pool that keeps changing
Deploying by SSH fails the moment the group scales out, because a new instance is built from the image and comes up running old code. The image is the deployment unit: build a new one, update the launch template, then run an instance refresh so nodes are replaced in batches while the balancer holds traffic on healthy ones. With DISALLOW_FILE_MODS set, plugin updates also stop happening in wp-admin, which the client needs to hear before launch.
5. Cache invalidation across nodes
Publish a post and only the node that handled the request purges its page cache. The others keep serving the old version, and the client reports content changing on refresh. Either hold no page cache on the instances and let a CDN keep the only copy, purging on publish through its API, or keep local caches under five minutes and accept brief inconsistency. The edge and origin split is covered in how CDN and caching work together, and on a multi-node build the edge should do most of the work.
What it costs: a worked example
Illustrative round figures for one US region in August 2026, on-demand, excluding data transfer, backups, support and tax. They show the shape of the bill, not a quote. Check the provider’s calculator for real numbers.
| Line | One large instance | Auto scaling pool |
|---|---|---|
| Web tier at idle | 1 x 8 vCPU / 16 GB, $248 | 2 x 4 vCPU / 8 GB, $248 |
| Load balancer | None | $25 |
| Managed database | On the same box, $0 | $95 |
| Managed Redis | On the same box, $0 | $29 |
| Object storage and CDN | $0 | $10 |
| Monthly at idle | $248 | $407 |
| Peak: 4 extra nodes for 40 hours | Not possible | $27 |
| Monthly with real peaks | $248 | $434 |
The pool costs roughly 65 percent more at idle and 75 percent more in a busy month. Auto-scaling is not a cost optimisation at this size. It buys two things a single instance cannot offer at any price: no single point of failure, and absorbing a three times spike without a human awake.
The economics flip at both ends: below this scale the single instance wins outright, and well above it, where peak is ten times baseline, permanently provisioning for four hours a week becomes the expensive option. It is the same trade-off set out in pay-as-you-go against fixed cloud pricing.
DIY, Cloudways or Kinsta
| DIY raw infrastructure | Cloudways | Kinsta | |
|---|---|---|---|
| Setup effort | High: you build and own every component | Low to moderate | Almost none |
| True horizontal scaling | Yes, entirely yours to configure | Not on standard plans; separate autoscaling and managed cloud products | Handled at platform level, not user configurable |
| Cost model | Per resource, pay-as-you-go | Fixed monthly per server plus add-ons | Plan tier by traffic and sites |
| Who it suits | Teams with DevOps capability and a real need | Agencies wanting managed servers without running infrastructure | Sites that want spikes absorbed with no configuration |
Being precise about Cloudways matters more than making it sound better than it is. The standard product is a managed VPS on DigitalOcean, Vultr, Linode, AWS or Google Cloud, and scaling there is vertical: you resize the server. That raises the ceiling without removing the single point of failure.
So the accurate recommendation is narrower than this article used to make. Cloudways is a strong choice when you want managed servers, staging and predictable monthly cost without running infrastructure yourself, and it is the wrong answer when the requirement is specifically an auto-scaling pool behind a load balancer. Confirm which product you are buying before promising a client high availability. How the per-server cost works out is covered in the comparison of Lightsail, DigitalOcean and Cloudways.
Kinsta sits at the other end: each site runs in a container on Google Cloud with Cloudflare in front, and capacity is handled at platform level. You configure no balancer and no scaling group because you have no access to one. For most sites that is the right trade, until you need a custom health check or your own deployment pipeline.
When not to build this
Most sites asking for auto-scaling need a caching layer and a bigger instance. If a site struggles at 500 concurrent visitors with no CDN, no object cache and an unoptimised database, horizontal scaling just multiplies an inefficient stack.
The genuine cases are narrow: uptime one instance cannot meet, spikes a CDN cannot absorb because the traffic is logged-in or transactional, or downtime that costs more per hour than a year of the hosting difference. Everything else is better served by the path in scaling WordPress hosting as an agency grows, or by a properly specified managed platform from the guide to cloud hosting for WordPress.
Frequently Asked Questions
Can WordPress run on multiple servers behind a load balancer?
Yes, but not unchanged. The database, uploads directory and object cache must move off the instances first, so any node can serve any request and losing one loses nothing. Skip that work and uploads and sessions appear and disappear depending on which server answered.
What CPU threshold should trigger auto-scaling for WordPress?
Around 60 percent average, and ideally as a backup to a requests-per-target policy rather than the primary signal. WordPress exhausts PHP-FPM workers before it saturates CPU, so CPU alone reacts late. The gap to 100 percent is the runway while a replacement boots and passes health checks, which takes three to five minutes.
Do I need sticky sessions for WooCommerce behind a load balancer?
Only if something uses PHP native sessions. Carts held in the database or shared Redis work from any node, which keeps traffic evenly distributed. Where a plugin requires native sessions, enable stickiness with a short duration and treat it as temporary, since removing an instance drops the sessions pinned to it.
How do I stop WP-Cron running on every instance?
Set DISABLE_WP_CRON to true, then run the queue from exactly one place: a utility host outside the scaling group, or a scheduled task calling WP-CLI every few minutes. Leaving the default on a pool means the same event fires once per instance, which on an order or subscription workflow means duplicated actions.
Does Cloudways support true auto-scaling for WordPress?
Not on the standard managed VPS plans. Those scale vertically: you resize one server, which raises the ceiling but leaves a single point of failure. Horizontal scaling across a pool comes from their separate autoscaling and managed cloud products, so confirm which you are buying before promising high availability.
Externalise state, health check something that proves PHP and the database are alive, scale on requests rather than CPU, and solve cron, disk writes, sessions, deployment and cache invalidation before launch. If that reads as more operational work than the site justifies, that is the correct conclusion, and a larger single instance behind a CDN is the better decision.
Need a WordPress developer?
Let's build something fast, scalable, and SEO-ready — from a custom theme to a full headless stack.
Get in Touch